Nvidia has released a new open-source communication primitive, Reshard collective, that sharply reduces the time and bandwidth needed to move updated model weights between training and inference GPUs in reinforcement-learning systems.
Nvidia releases Reshard to speed AI weight transfers
That matters because weight refit has become a real bottleneck as frontier AI models swell into the trillions of parameters and RL training loops demand frequent parameter transfers to generate fresh trajectories. Nvidia says its approach can cut synchronization overhead enough to trim total RL step time by 12.7% on a 256-GPU NVL72 cluster, giving the company another way to make its hardware more valuable in the fastest-growing part of AI infrastructure.
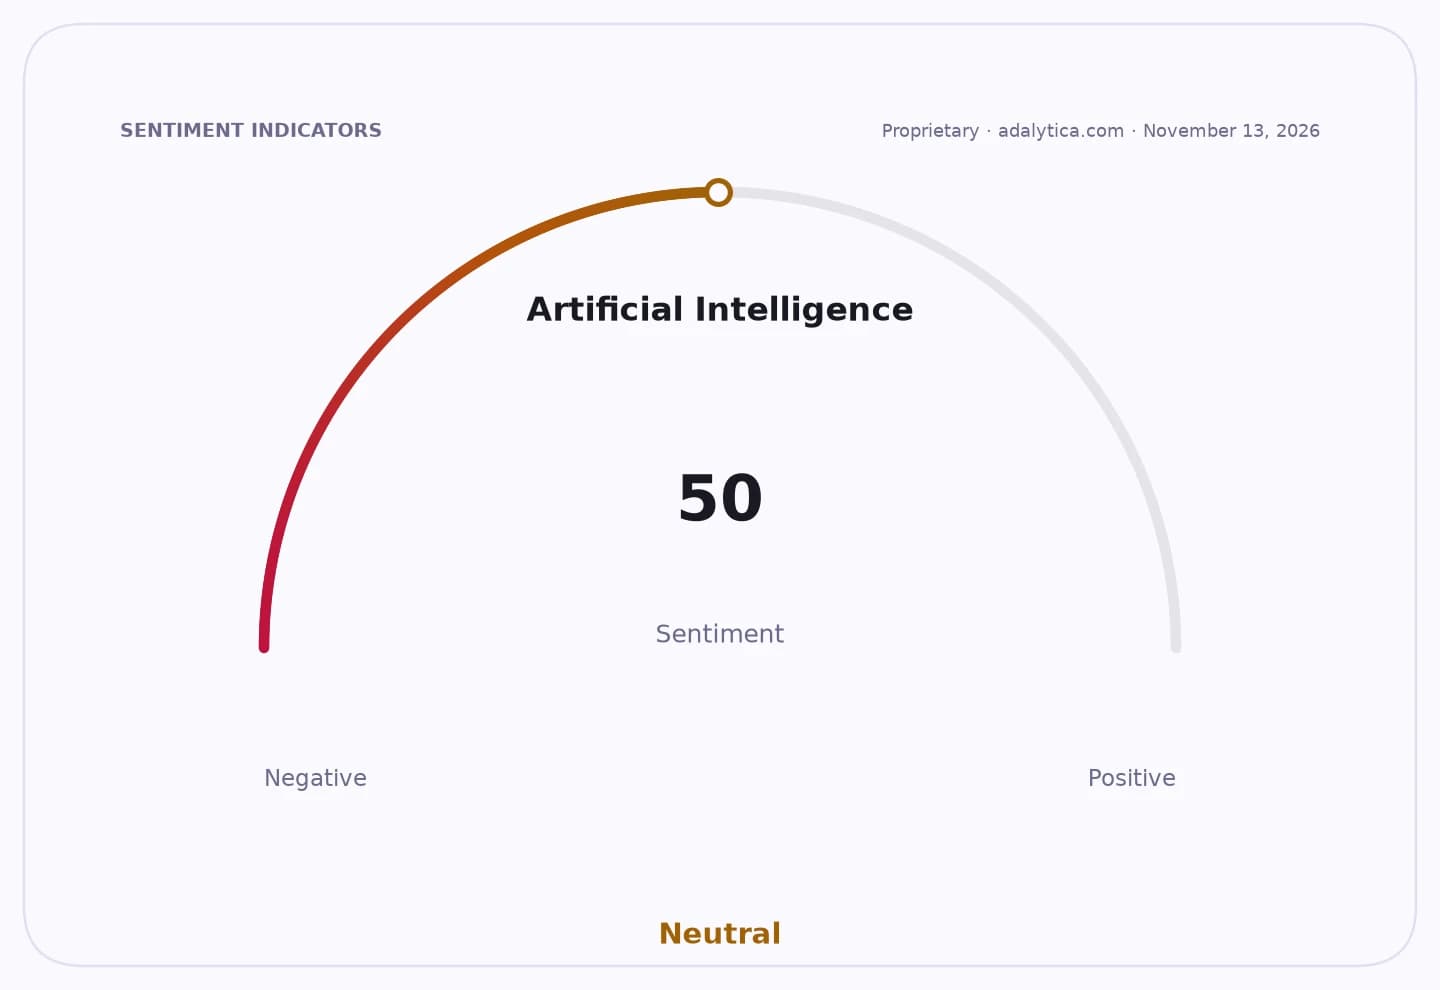
Sentiment Indicators
In internal tests on DeepSeek-V3, a 671-billion-parameter model, refit latency fell to 2.6 seconds on DGX H100 systems from 14.9 seconds under older methods, while latency on DGX GB200 systems dropped to 2.3 seconds from 6.1 seconds. Nvidia also said a single feed-forward mixture-of-experts layer transfer improved to 9.8 milliseconds from 77.3 milliseconds using flat direct sends.
The technical pitch is straightforward: instead of reconstructing full tensors and broadcasting them to inference GPUs, Reshard uses PyTorch’s distributed tensor abstraction to move shards directly from one GPU set to another. Nvidia says that avoids redundant communication and becomes increasingly important as model sizes expand; for a 2.8 trillion-parameter model such as Kimi K3, it estimates roughly 11.2 terabytes of communication payload per refit under conventional BF16 weight transfer.
For investors, the significance is less about the code itself than what it says about Nvidia’s business model. The company is trying to keep its chips indispensable not only for training giant models, but also for the infrastructure layer that keeps RL systems efficient enough to run at scale. That supports demand for Nvidia’s GPUs, networking gear and software stack even as customers push to lower compute costs per token and per training step.
The release also fits a broader pattern of Nvidia moving deeper into AI operations tooling, including the use of AI agents to help optimize DGX SuperPOD operations. By turning a performance pain point into an Nvidia-specific software advantage, the company strengthens its ecosystem pitch against rivals trying to commoditize AI compute.
Nvidia’s stock has been under heavy pressure recently, with standard technical indicators showing the shares well below the 50-day moving average and the relative strength index in oversold territory. The stock’s latest slide underscores how quickly sentiment can swing even around a company still positioned at the center of AI spending.
The open-source release through Nvidia’s NCCL extensions repository could make the technology easier to adopt in frameworks such as NeMo RL and vLLM. The next test is whether customers treat Reshard as a useful optimization or as another reason to build deeper into Nvidia’s software platform.
| Entity | Gains | Losses |
|---|---|---|
| Nvidia | ▲Higher platform stickiness | ▼Less software differentiation for rivals |
| AI model builders | ▲Lower RL refit latency | ▼More complexity in custom stacks |
| Cloud/inference operators | ▲Better GPU utilization | ▼Old broadcast-heavy workflows |
| Competing chip vendors | ▲— | ▼Nvidia ecosystem advantage |